Why your busiest Postgres table is mostly dead rows
A table with a few million rows takes up far more disk than the data justifies, and queries on it have slowed down for no obvious reason. In PostgreSQL the usual reason is dead row versions that vacuum has not been able to reclaim.
Why dead rows exist
PostgreSQL uses multiversion concurrency control. An UPDATE does not change a row in place. It writes a new version and marks the old one as no longer visible to new transactions. A DELETE only marks the row. The old versions have to stay until no running transaction could still need them, and then vacuum can reuse their space. A table that is updated constantly, such as a counters table, a job queue or a session store, produces dead rows at the rate of its updates.
How autovacuum decides
Autovacuum starts on a table when the number of dead rows exceeds autovacuum_vacuum_threshold (default 50) plus autovacuum_vacuum_scale_factor (default 0.2) times the row count. On a table with 100 million rows, that is about 20 million dead rows before it even starts, and by then the table is already bloated and the vacuum run is long. The defaults are fine for small tables and too lazy for large ones.
Per-table settings fix this without changing the whole server:
ALTER TABLE events SET (
  autovacuum_vacuum_scale_factor = 0.01,
  autovacuum_vacuum_threshold = 10000
);
Look at what is happening
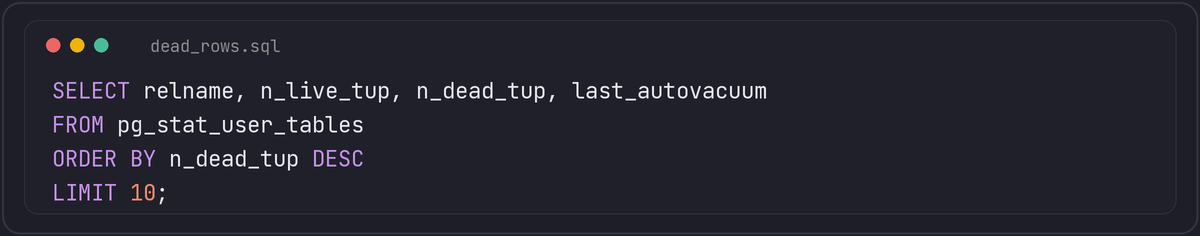
If n_dead_tup is large compared with n_live_tup and last_autovacuum is old, autovacuum is not keeping up or is being blocked.
What blocks cleanup
- Long-running transactions. A transaction that stays open, including one sitting
idle in transaction, forces PostgreSQL to keep every row version newer than its snapshot. One forgotten session in a notebook can hold back vacuum on every table. Find them inpg_stat_activityand setidle_in_transaction_session_timeout. - Replication slots and standby feedback. An unused or lagging replication slot, or a standby with
hot_standby_feedbackon that runs long queries, can hold back the cleanup horizon as well. - Autovacuum being throttled. By default it sleeps between chunks of work to limit I/O. On fast storage, raising
autovacuum_vacuum_cost_limitlets it finish sooner.
Reclaiming space
Plain VACUUM marks space reusable inside the table but normally does not return it to the operating system. VACUUM FULL rewrites the table and does return it, but it takes an ACCESS EXCLUSIVE lock for the duration, which blocks reads and writes. For a live table, the pg_repack extension can rebuild it with much shorter locks. Often the better answer is to stop the bloat from accumulating: tune autovacuum for the table, avoid updating rows that have not changed, and keep transactions short.
Fillfactor and HOT updates
If an update does not change any indexed column and the new row version fits on the same page, PostgreSQL can do a heap-only tuple (HOT) update, which avoids touching the indexes and is cheaper to clean up. Leaving some free space on each page with a lower fillfactor (for example 80 on a hot-updated table) makes HOT updates more likely.
A small worker pool for potentially many bloated tables
Per-table thresholds decide when a table qualifies for cleanup, but autovacuum_max_workers (default 3) limits how many tables autovacuum works on at the same time across the whole cluster. If several large tables cross their threshold together, for instance after a bulk load touches many of them, the extra ones simply wait their turn behind the ones already being processed. A database with many large, frequently updated tables can need a higher worker count than the default, alongside the per-table tuning shown above, or the tables at the back of the queue keep bloating while autovacuum is busy elsewhere.
A related, separate setting is worth not confusing with the vacuum thresholds: autovacuum_analyze_scale_factor and autovacuum_analyze_threshold control when statistics are refreshed, not when dead rows are cleaned. A table can be vacuumed on a reasonable schedule while its statistics still drift, which shows up as the planner problems covered in the EXPLAIN article rather than as bloat. The two settings are tuned independently, and it is easy to fix one and assume the other followed along.